Put your expertise to work at greater scalePut your expertise to work at greater scalecapacityefficiencyspeed
We start with what you want to achieve. You may want to lower the cost of delivery, give your people better tools, improve a product or service, or explore something new.
We design, build and improve AI systems around your knowledge, methods and tools. They can learn to apply your expertise and carry out work autonomously. You decide their authority and when to involve your people.
You own the code we build for you and the deployment that runs it. We can continue developing the system with you as your business evolves.
“Alf is proactive at working with the entrepreneurs to organise their business proposition, and is up-to-date with latest tools and technology. Alf pulls a build plan together which fits seamlessly into the commercial plans.”
Stuart Laird-Smith Co-founder, stealth startup in the UAE
The harness factory
A harness is the software that enables an AI model to carry out work. It connects the model to your information and tools, manages how work proceeds and checks the result. It also defines what the system can do on its own and when to involve your people.
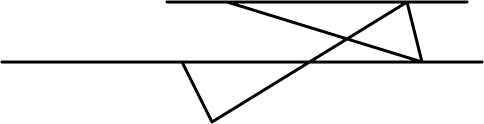
A Jacquard harness is the system of cords connecting a loom's selecting mechanism to its warp, the lengthwise threads of the fabric. Punched cards determine which threads are raised as the loom weaves. The arrangement of the cords allows a selection to produce repeated or mirrored patterns across the cloth. Jacquard's punched-card principle also influenced Charles Babbage's design for the Analytical Engine. This illustration is a simplified study after E. A. Posselt's 1888 diagrams.
Kylace builds the software harness around AI models. We connect them to your data and tools, define how work proceeds, and build in checks and human approval where needed. The connection to the loom is deliberate configuration: the system around a source of capability is designed for the work it must complete.
This evaluation compared model configurations for a production agent that helped users check financial data. It used 22 real user tasks with automated checks for answer accuracy and tool use. The cost comparison uses mean inference cost per task attempt, calculated from recorded token use with cached input on 9 September 2026. An attempt covers one user task and may include several model requests. It includes failed attempts and does not establish equal reliability.
86% lower inference cost per attemptMean inference cost per attempt for the selected configuration.
“Reference data as an engineering advantage” compares a task-specific reference tool with general SQL access to the same production records. GLM 5.3 Flash through Baseten was evaluated on 20 held-out reconciliation tasks, each covering 50 agreements, with 5 attempts per task and toolset, on 25 September 2026. Reference tools produced 99 correct tables in 100 attempts. General SQL produced 99 in 100. These observations do not establish equal reliability. Each plotted point is a task mean. Cost views omit one mean with an incomplete usage receipt.
48% fewer model requests per attempt2.03 requests per attempt with reference tools, 3.90 with general SQL.
See how the reference query was designed, tested and measured. Read the study